Docs and runbooks people actually read
Docs-as-code, runbooks and decision records that stay up to date.
Docs-as-code, runbooks and decision records that stay up to date.
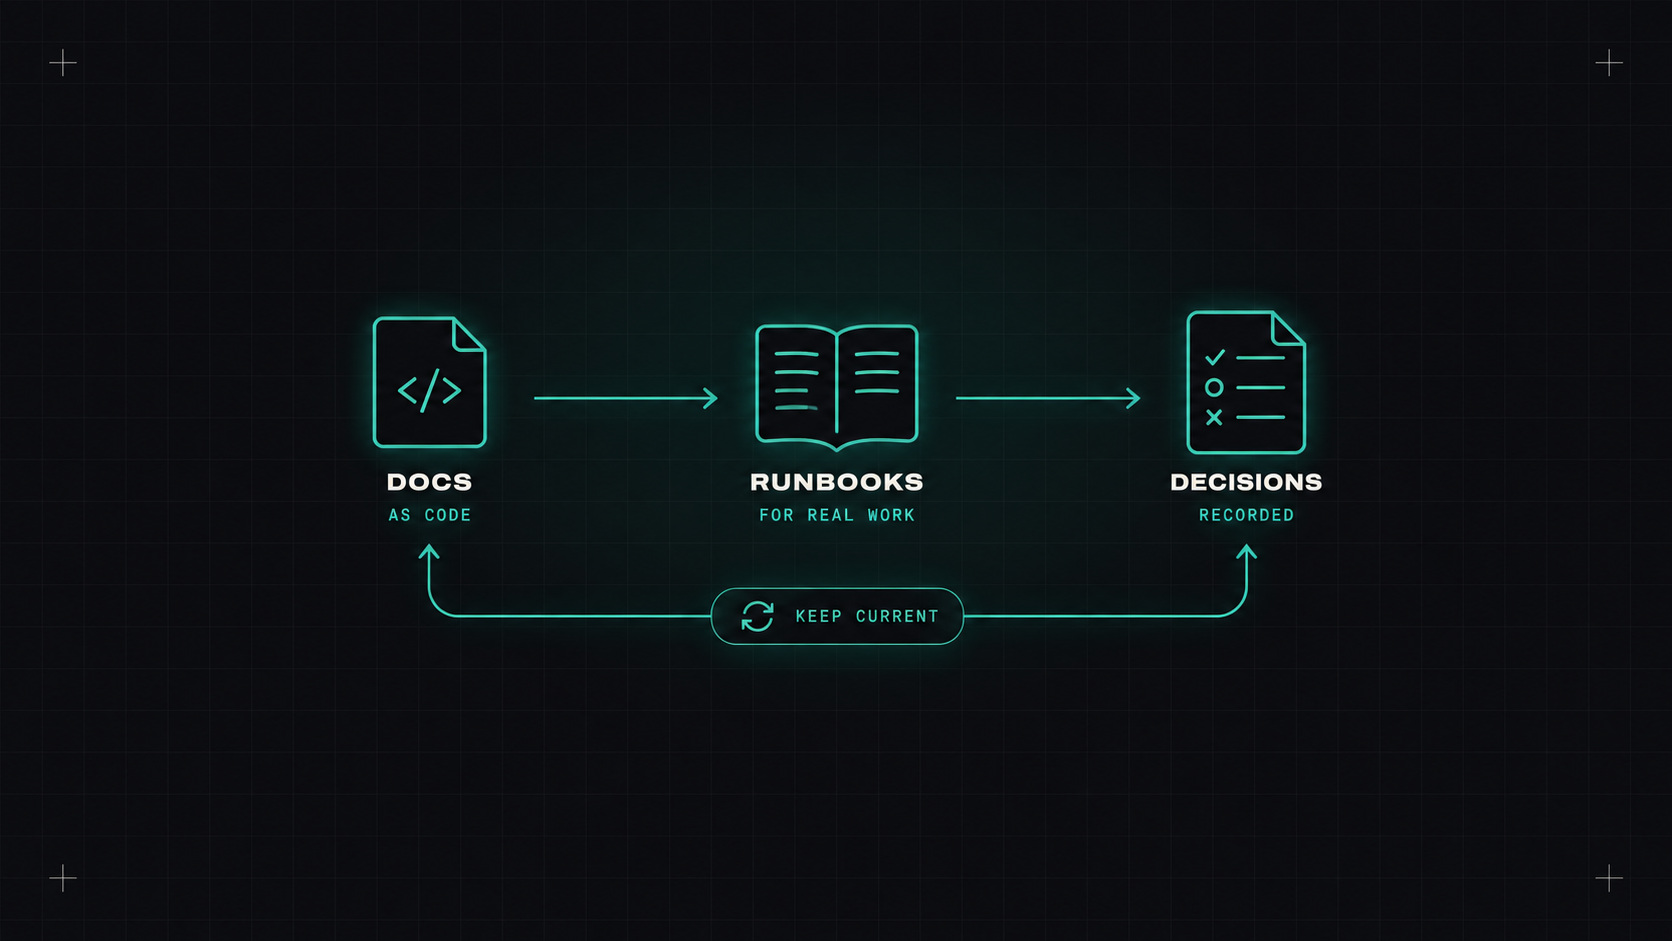
Every team says they value documentation. Then you open the wiki and find pages last updated three years ago, instructions for servers that no longer exist, and a page titled "TODO: write this" from someone who left in 2023.
Bad documentation is worse than none, because people trust it and follow it. But good documentation is one of the highest-leverage things a DevOps team can produce. It's how knowledge survives holidays, sick days and people moving on.
Here's how to write docs that stay useful.
Docs-as-code means treating documentation like code:
Tools that make this easy:
A pull request template with a checkbox "documentation updated (or not needed)" is a small nudge that helps a lot.
The best time to update documentation is in the same pull request that makes it wrong.
Runbooks are the most important docs for operations. When an alert fires at 3 a.m., the on-call engineer needs answers fast, not prose.
My template:
# Alert: CheckoutHighErrorRate

## What it means
More than 2% of checkout requests return 5xx errors over 5 minutes.

## Impact
Customers can't complete purchases. Revenue impact. Treat as SEV2 or higher.

## Check
1. Dashboard: [Checkout overview](https://grafana.example.com/d/checkout)
2. Recent deployments: `kubectl rollout history deploy/checkout -n shop`
3. Errors by endpoint: [Logs query](https://grafana.example.com/explore?...)
4. Payment provider status: https://status.paymentprovider.example

## Common causes and fixes
- **Bad deployment** → roll back: revert the commit in the GitOps repo
  (or `kubectl rollout undo deploy/checkout -n shop` in an emergency).
- **Payment provider outage** → switch to backup provider via feature flag `payments.fallback`.
- **Database connection exhaustion** → check `orders-db` connections dashboard; scale checkout down
  temporarily or restart the connection pooler.

## Escalation
- Checkout team: @checkout-oncall
- Database: @dba-oncall
- Incident commander for SEV1: use `/incident declare`

## Last reviewed
2026-09-15 by @desly
Key principles: link directly to dashboards and queries, give copy-paste commands, list common causes first, and say who to call. And link the runbook from the alert itself.
Six months after a decision, nobody remembers why it was made. "Why do we use Loki and not Elasticsearch?" "Why is this service on its own cluster?" Without a record, teams either repeat old debates or undo good decisions by accident.
Architecture Decision Records (ADRs) solve this. An ADR is a short document, usually one page, stored in the repository:
# ADR-012: Use Gateway API instead of Ingress for new services

## Status
Accepted (2026-05-04)

## Context
ingress-nginx was retired in March 2026. We need a supported way to route traffic.

## Decision
New services use Gateway API with Envoy Gateway. Existing Ingress resources
are migrated by end of Q3.

## Consequences
+ Supported, portable API with role separation.
- Teams need to learn HTTPRoute; some annotations need manual migration.
Numbered, short, never deleted (superseded ADRs are marked as such). Tools like adr-tools or Log4brains help, but a folder of Markdown files works perfectly.
AI tools are great at drafting documentation: summarising a codebase, turning an incident timeline into a runbook, explaining a complex config. Use them for first drafts. But a human who knows the system needs to check every step, because a wrong runbook at 3 a.m. is worse than none.
Write runbooks for your five most frequent alerts, with the template above, and link them from the alerts. Then start an ADR folder and write the first record about the next decision your team makes.
My take: documentation is a gift to your future self and your colleagues. Keep it close to the code, keep it short, and keep it true.
— Desly